One sentence in my most-cited paper
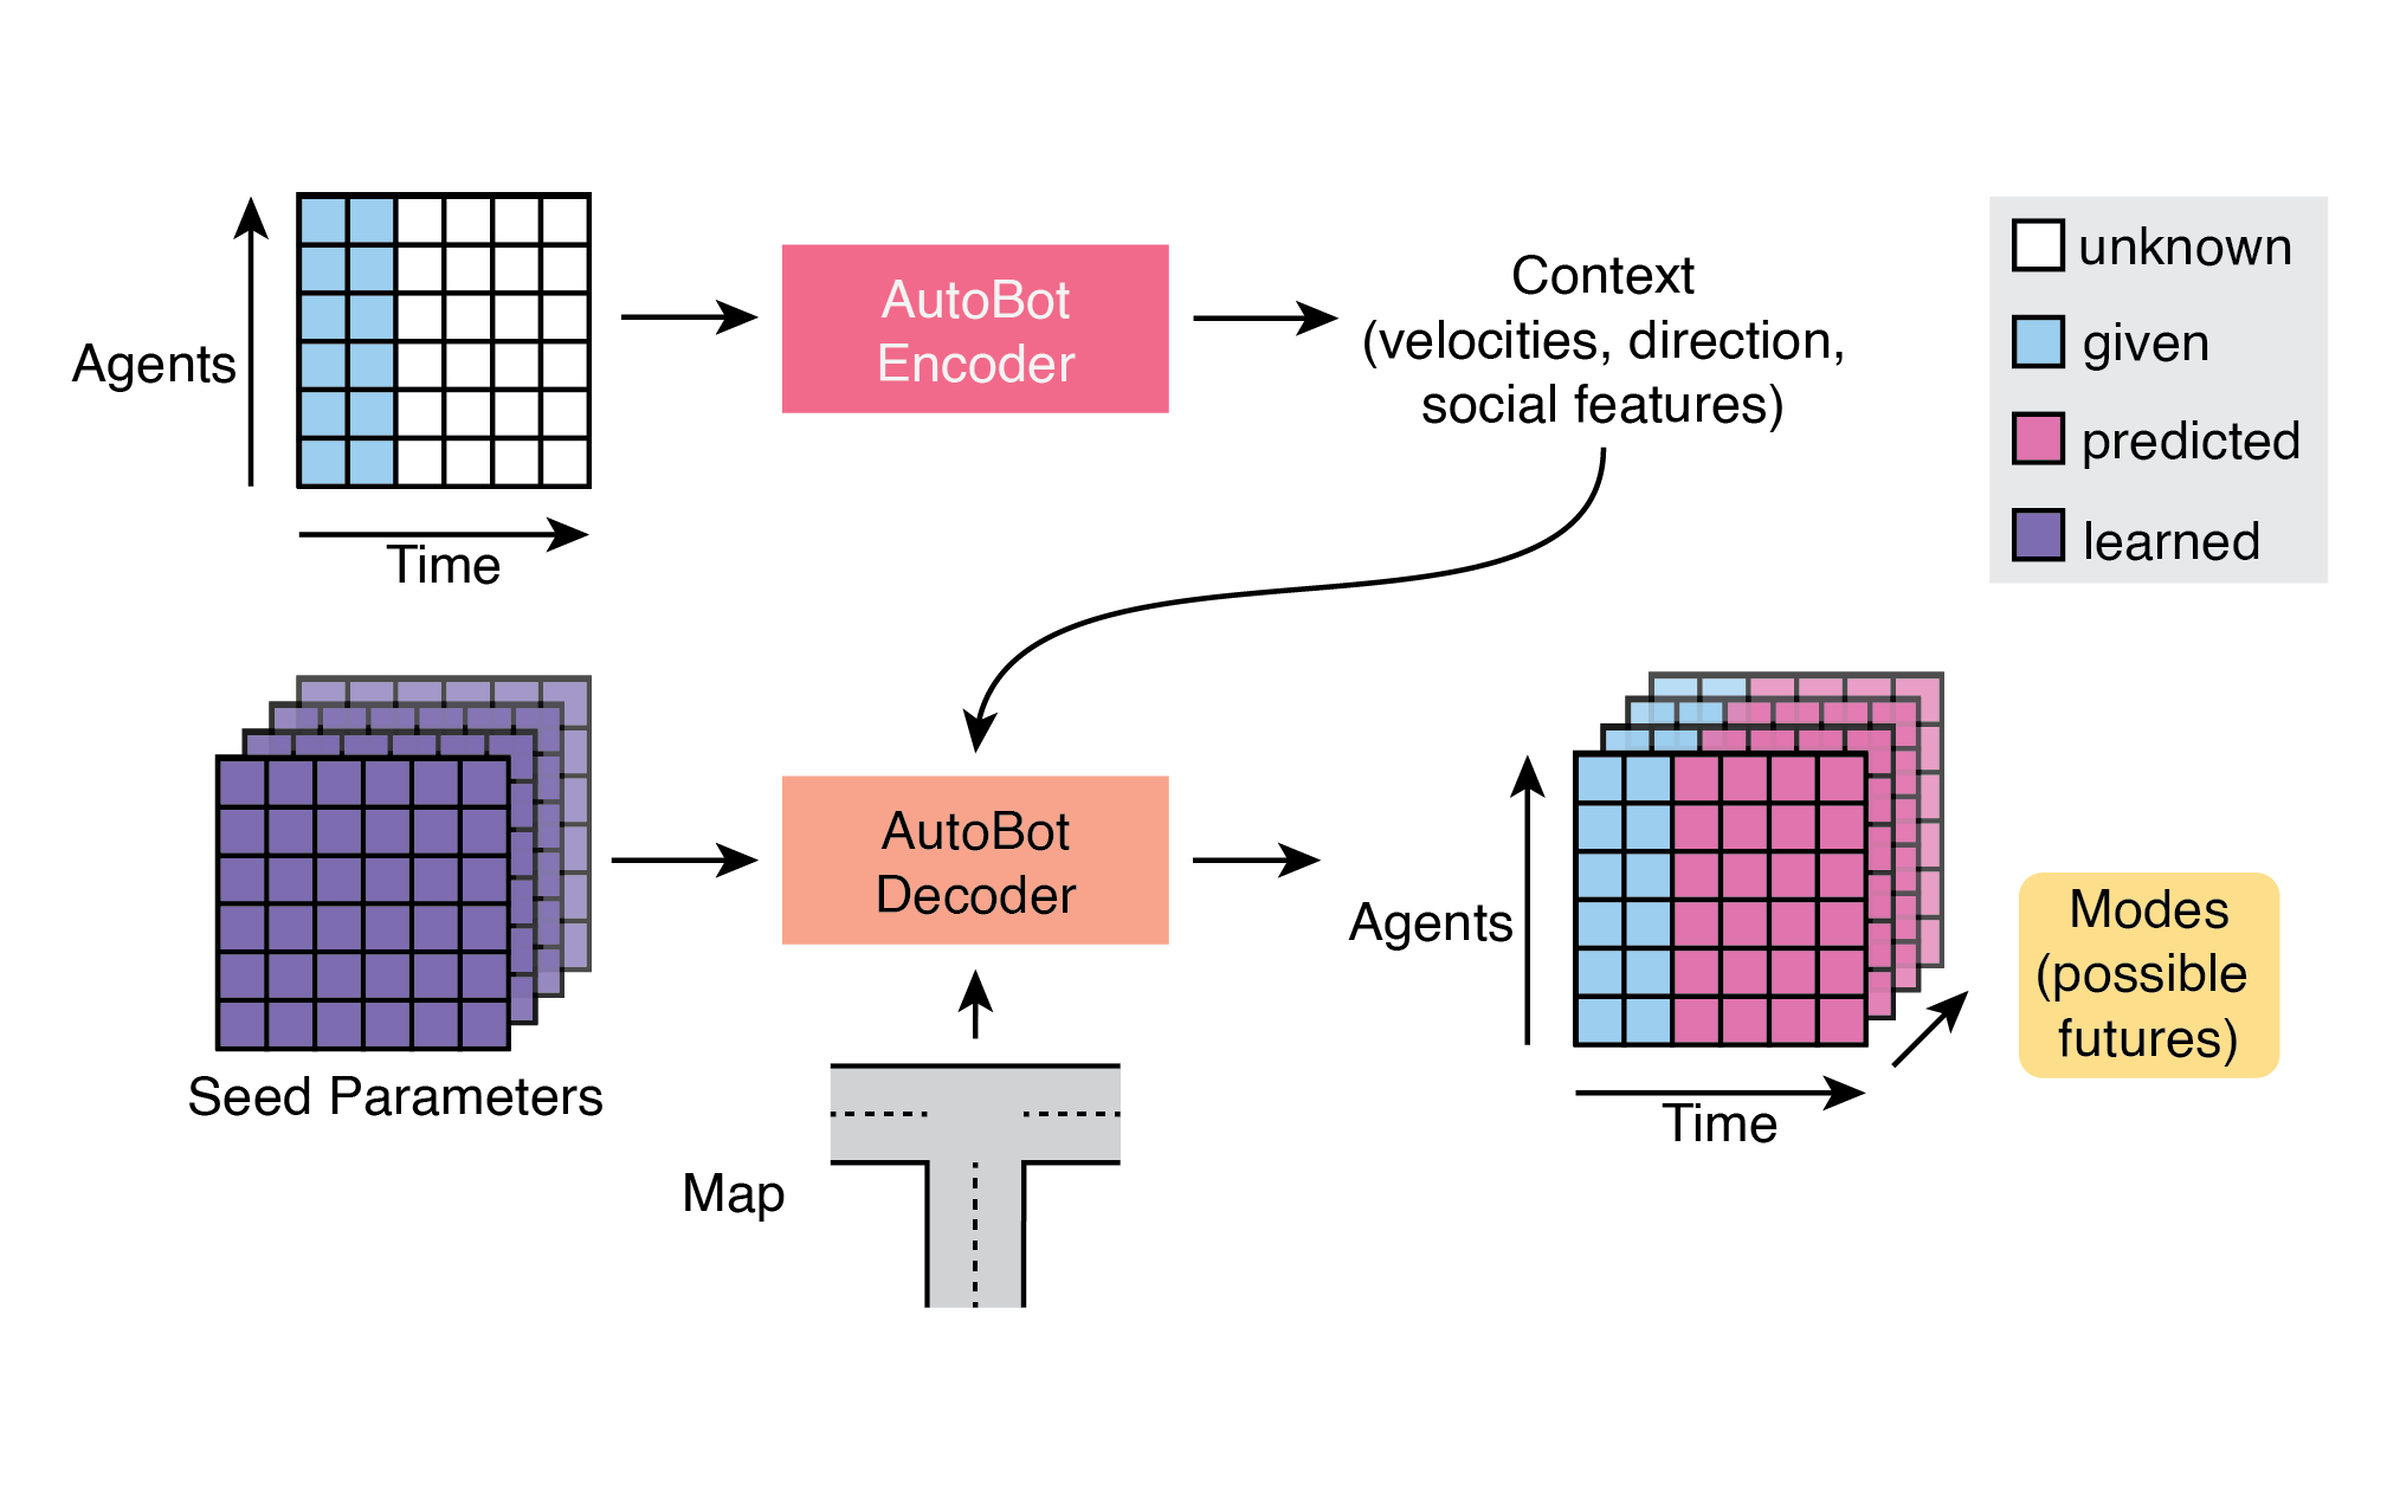
My main contribution to the most-cited paper with my name on it is a single sentence in the abstract.
My contributions were:
- A proof in the appendix that the method is permutation equivariant over agents. Pretty trivial, frankly.
- The last sentence of the abstract: “A distinguishing feature of AutoBots is that all models are trainable on a single desktop GPU (1080 Ti) in under 48h.”
AutoBots (ICLR 2022 spotlight) is Roger Girgis’s paper. I’m 4th of 8 authors. I didn’t train the model, but I did get that sentence added.
Roger is a longtime friend, and this was more than half a decade ago when we were just starting grad school. I knew he was doing research on his desktop at home and that he wasn’t comfortable using the compute cluster yet. I was still using a Lenovo ThinkPad, FWIW.
Still, he achieved SOTA on the extremely competitive NuScenes motion prediction leaderboard.
He asked me to contribute a proof to the paper, and I happily spent a week writing it up. When joining the project meetings, I realized that Roger hadn’t told the team how little compute he was using.
For context, AutoBots was competitive with Scene Transformer, developed by a team of 14 researchers at Waymo and Google Brain using roughly 250× more compute.
Roger had done something remarkable, and almost left one of the most remarkable things about it out of the paper. I confirmed with him where he was training the model, he shared it with the team, and we added it to the paper.
Sometimes your constraints are what lead to the best innovations. There’s also something here about being open to being vulnerable. Using less compute made the paper stronger.
- Paper: arxiv.org/abs/2104.00563
- Code: github.com/roggirg/AutoBots
- Lacuna: Latent Variable Sequential Set Transformers for Joint Multi-Agent Motion Prediction
First posted on LinkedIn, October 20, 2026.